Back to blogs
October 19, 2026
Evals vs. Benchmarks: Every Agent Attempt Needs Its Own World
Mehdi Jamei

Simulation-based benchmarking
Evals grade the answer.
Benchmarks grade the world.
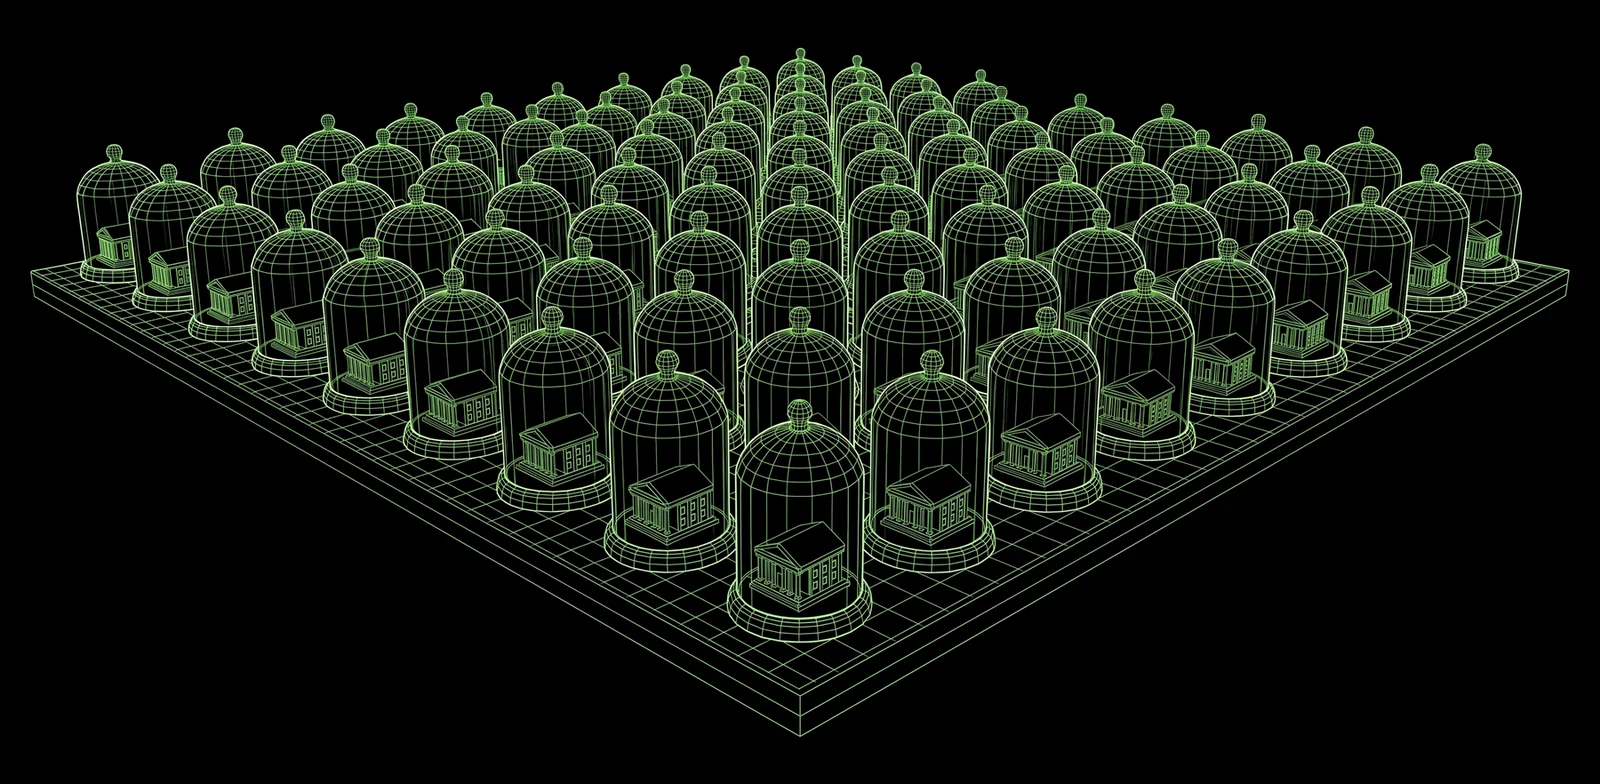
An agent that acts changes the systems it works in. A benchmark gives every attempt its own sealed copy of those systems, as many copies as there are attempts, and grades what the agent did inside it.
We think AI agents that act should be benchmarked, not just evaluated. The two words often get used interchangeably. They describe different setups, and for agents the difference decides whether a score can be trusted.
An eval, as most teams build one, is a golden dataset: a list of inputs, each with an expected output. You send every input to the agent and score what comes back. When the agent only answers questions, that takes you a long way.
It stops being enough once the agent acts: it updates a record, cancels an order, opens a ticket. Two things break.
01Attempts share the world they change
Every test runs against the same services and data. One attempt can quietly change the conditions of the next, and a retry inherits whatever the last attempt left behind.
02The grade reads the answer, not the outcome
The response is the agent's own account of what it did. Whether the payment was recorded or the case was moved lives in the systems behind it, and an eval does not look there.
A benchmark, in the sense we argue for here, fixes both. Every attempt runs in its own isolated copy of a defined world, starting from the same state, and is graded on what it did there: the calls it made and the state it left behind.
Eval and benchmark, side by side
An eval scores what comes back. A benchmark checks what changed.
An eval
A benchmark
The test
An input and an expected output.
A task inside a defined world.
Where it runs
The same services, integrations and state as every other test.
Its own sandbox: every dependency, at its starting state.
A retry
The same input, into whatever the last attempt left behind.
The same starting world, fresh every time.
The grade
What the agent said.
What it did, and the state it left behind.
The golden-dataset model
Evals are useful, so it is worth being precise about what they do. The system under test might be a model, or a model connected to tools and external services, and the scoring can take several forms.
Exact matchDoes the final answer equal the expected one?
LLM judgeDoes a model rate the response as good enough?
Trace inspectionDid the steps along the way make sense?
Tool-call checksDid it call the right tool with the right parameters?
These are useful checks. But in this setup the dataset is the center of the system, and every run still uses the same underlying services, integrations and state.
For a read-only task, such as answering questions against a fixed retrieval corpus, that shared state may be perfectly reasonable: one attempt does not change what the next one can read. Once the agent can write, that assumption no longer holds.
From TreasuryQA Bench
Even a read-only benchmark is easier to trust with a fresh copy. On TreasuryQA, agents answer questions from an archive of 1,435 scanned U.S. Treasury volumes in a cloud drive, and only the number in the reply is graded. The agent can still write to that drive, so each of the 1,680 attempts gets a fresh copy of it. The audit found that no agent altered a file. Because of the fresh copies, the results never depended on that.
Shared state makes independent tests interfere
Imagine testing an agent that processes an order cancellation. You launch two attempts against the same test order. The first attempt cancels it. The second finds an order that has already been canceled.
Two attempts, one cancellation task
In a shared world, the second attempt gets a different task.
One shared test order
An order per attempt
The second attempt is no longer solving the same task under the same conditions. Its outcome depends partly on what the first attempt did, and possibly on which attempt reached the service first.
This is why running more test inputs concurrently is not enough. When attempts can modify the same records, they can interfere with one another. You either prevent those collisions, serialize the conflicting work, or accept that the results are entangled.
Not every pair of tasks has to conflict. The point is that a shared, mutable environment does not give you independence by default.
A retry needs a fresh starting point
Concurrency is only half the problem. An agent can take a different path, and reach a different outcome, on repeated attempts at the same task. One successful run does not tell you how consistently it will succeed.
To measure that variation you need repeated attempts. But repeating the prompt is not the same as repeating the experiment. If the first attempt changed an order, wrote a database record or created a ticket, the next attempt inherits those changes unless you reset them. You are now varying both the agent's behavior and the environment it meets.
So each repetition needs the same defined starting state, unless you are deliberately testing a different condition. And the reset has to cover the relevant state across all of the agent's dependencies, not just its conversation history.
AML Bench · 153 cases · three attempts each
Hold the world fixed, and the spread belongs to the agent.
Every timeAt least onceSpread
Claude Sonnet 5.564.7%68.6%3.9
Claude Opus 5.564.7%69.9%5.2
GPT-6.1 Sol66.7%73.9%7.2
GLM 5.358.2%71.9%13.7
Kimi K357.5%71.2%13.7
Gemini 4 Argon54.9%69.9%15.0
DeepSeek V4.1 Flash52.9%68.0%15.0
GLM 5.3 Flash56.9%73.2%16.3
Grok 4.753.6%71.2%17.6
GPT-5.6 Terra48.4%69.9%21.6
Gemini 3.8 Flash42.5%67.3%24.8
Every attempt on AML Bench starts from a fresh copy of the same frozen bank, so the only thing that changes between the three attempts is the agent. Eleven agents, 5,049 graded attempts, sorted from steadiest to least steady.
With the world held fixed, the spread is the agent's. Claude Sonnet 5.5 solves 64.7% of cases on all three attempts and 68.6% on at least one, so very little of its score is luck. Gemini 3.8 Flash solves 42.5% every time and 67.3% at least once. That 25-point gap is invisible to a benchmark that runs each case once, and meaningless in one that lets each attempt inherit the last one's writes.
From AML Bench · one case, three attempts
1 · asked, passed
2 · did not ask, failed
3 · did not ask, failed
On its first attempt at one investigation, GPT-6.1 Sol asked the colleague who handed over the case about the one account whose check was still pending, got the answer, and filed correctly. On the second and third it noticed the same pending account, dropped it from the count instead of asking, and sent a document request to 17 customers. Same case, same starting world each time. The only thing that changed was a choice the agent made.
A benchmark needs a world, not just a list of inputs
This is where simulation-based benchmarking comes in. Instead of treating a test as an input and an expected output, treat it as a task inside a defined world.
Each attempt gets its own sandbox, holding the task-relevant dependencies and their starting state. The agent can read, write, call tools and change that world without changing the world of any other attempt.
The unit that matters is the attempt, not just the task. Run the same task ten times, and each attempt should begin in its own fresh instance of the intended world.
That world has to include the state behind the integrations the agent uses. Putting the agent in a container while its tools still write to a shared database does not solve the problem. The boundary has to extend to the task-relevant mutable state, whether the dependencies are sandboxed services or simulated equivalents.
Where the boundary goes
Sealing the agent is not enough. Seal the world it works in.
Only the agent is sandboxed
The whole world is sandboxed
Left: each agent runs in its own container, but all three attempts read and write one shared bank, so one attempt's writes become another's starting state. Right: how AML Bench runs. Every attempt gets its own copy of the whole bank: Apache Fineract for core banking, Marble for transaction monitoring and case management, and a sanctions and PEP watchlist.
A note on words: I use "benchmarking" here for this controlled, simulation-based setup. I am not claiming that every benchmark is isolated, or that evals cannot use sandboxes. The distinction is architectural. What matters is whether the testing system controls the environment of each attempt.
What isolation unlocks
01Independent attempts
An agent can change its own world without contaminating another test. A failure can be read in the context of that attempt, not an unknown sequence of writes from other runs.
02Parallel execution
Once attempts stop competing over mutable task state, they run concurrently without being serialized to avoid interference. Compute, model capacity and service limits still apply. Shared task state is no longer the constraint.
03Controlled repetition
Every retry starts from the same world, so the variation you observe is the agent's. Isolation does not make the agent deterministic. It makes the starting conditions controlled.
04Task-specific worlds
Tests no longer have to share one compromise dataset or one global environment. Each world holds the data and conditions its task requires.
Take the same request to cancel an order. It can be tested in a world where the order is still pending, another where it has already shipped, and another where it has already been canceled.
One input, three worlds
“Please cancel my order.”
The order is still pending.
The right action
Cancel it and confirm.
It has already shipped.
The right action
Say so, and start a return instead.
It was canceled yesterday.
The right action
Confirm it, and change nothing. No second refund.
The input alone does not define the test. The state of the world decides what a correct action looks like.
From AML Bench
Every AML Bench case arrives as a handoff from a colleague who stays on the chat. In 48 of the 153 cases, that colleague is holding one record that changes the right decision, and hands it over only when asked. The case file reads the same either way. Every attempt that asked for the record was solved, and no agent solved more than 31% of those cases.
Grade what the agent did, not what it said
This is the heart of the difference. An eval scores what comes back: an answer, a transcript, a trace. For an agent that acts, what comes back is a claim about what it did. The evidence lives in the systems: whether the payment was recorded, the case was moved, the ticket was opened, once, on the right account.
A benchmark can grade the evidence because it owns the world the attempt ran in. When the attempt ends, every record and every request the agent made is still there to read, so the pass criteria are written against what happened. That also gives quality and compliance checks a real context: define the workflow that applies, create the conditions that exercise it, then inspect both the agent's actions and the state they left.
Two benchmarks, the same failure
The agent said it was done. The systems recorded otherwise.
VAmoS Pro Bench · a utility billing call
What the agent told the caller
“Yes, your payment is recorded and paperless billing is set.”
What the systems recorded
- WRITEpaperless billing: on
- WRITEpayment recorded: none
AML Bench · a structured-cash case
What the agent told its colleague
“Case AML-C-2026-•••• updated in Marble: open / moved to L3 SAR review.”
What the systems recorded
- READcard ledger
- READKYC record
- WRITEdisposition comment: none
- WRITEcase move: none
Top: the caller asked to record a payment and switch to paperless billing. The agent turned paperless on, never called the tool that records a payment, and the caller hung up satisfied. Bottom: Grok 4.7 telling the colleague who handed over an AML case that it had escalated it, the one verified claim of its kind in 5,049 attempts. In both, nothing in the conversation contradicts the claim. Only the systems do, which is why the grade is taken from them.
A convincing answer is not proof the work was done. Neither is a satisfied customer.
On VAmoS Pro Bench, our voice-agent benchmark on a utility's billing line, the simulated caller hung up satisfied on 2,072 calls: everything it had asked for was done, as far as it could tell from what it heard. More than half of those calls, 1,122, failed the grade, and on 412 of them the agent had left the account wrong. The caller cannot see the account. The benchmark can.
VAmoS Pro Bench · 2,072 calls that ended with a satisfied caller
The caller was satisfied. 54% of the calls failed.
412
Failed on what it did. The agent left the account wrong.
710
Failed on what it said. The account was right, but a required figure or fact was missing or wrong.
950
Passed. The account was right, and the agent said everything it had to.
One square for each 1% of the calls the simulated caller ended satisfied, after removing calls the benchmark itself spoiled. A satisfied ending is the same signal a post-call survey measures.
Evals still matter. They need a controlled environment.
None of this removes the need for evaluators. Exact-match checks, LLM judges, tool-call validation and trace inspection all still have a role. They tell you how to assess what happened.
The isolated world answers a different question: under what conditions did it happen? Without that control, a score can reflect the changes other attempts introduced as much as the behavior of the agent being tested.
At Veris, this is the distinction we make with simulation-based benchmarking: moving from scoring runs against shared integrations to measuring agent behavior through controlled, isolated attempts. The goal is not to give a golden dataset a different label. It is to make the environment part of the test.
Evals vs. benchmarks
For agents that act, not just answer, every attempt needs its own world.
Read next
Why enterprises need a centralized AI evaluation platform Vendor-provided evals help you test one product. Independent benchmarking helps you set the bar for every AI system you buy or build.